
This is Part 2 of a three-part series on data warehousing. Start with Part 1, What Is a Data Warehouse?; Part 3 covers the modern cloud data warehouse.
A data warehouse is a database built for analysis rather than transactions: a place where data from many separate systems is consolidated, cleaned, and stored so people can understand what's happening across the whole organization. Part 1 covered what that means and why it matters. This piece opens the box: how data actually gets into a warehouse, and how it's structured once it's there.
How a data warehouse is built: the moving parts
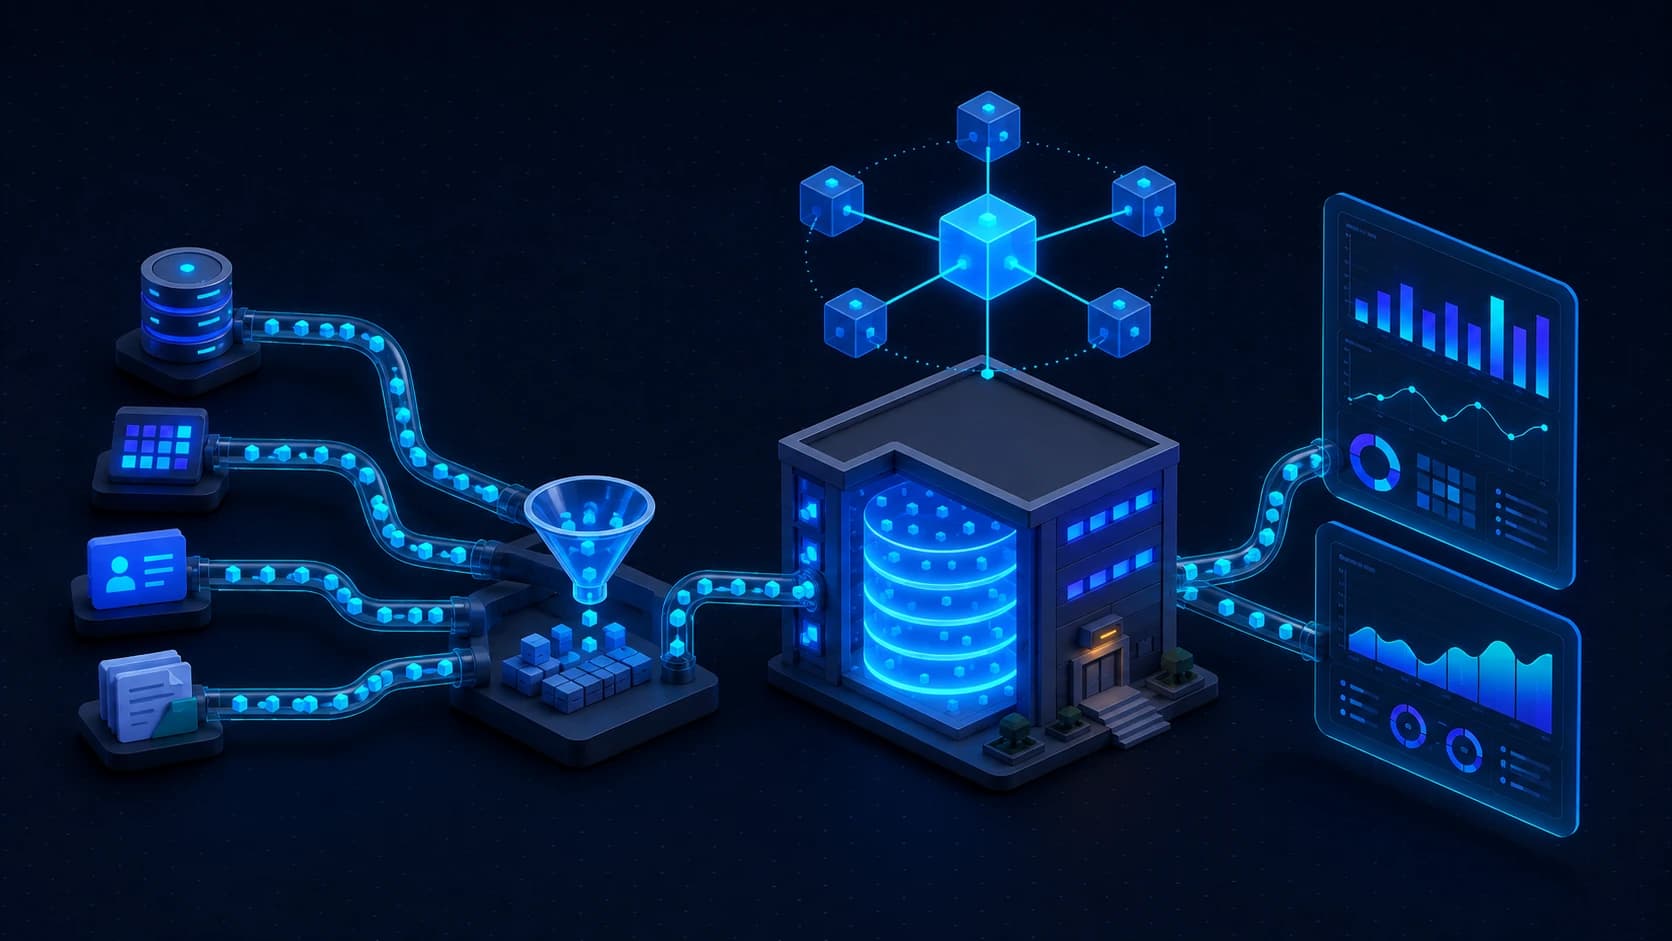
It helps to picture a warehouse as a pipeline with a few distinct stages.
Source systems. Data originates in many places, not just relational databases: SaaS applications, event and clickstream data, flat files, APIs, spreadsheets, and external feeds. Some of it is neatly structured; a growing share is semi-structured, such as JSON documents and logs.
Data integration (ETL or ELT). Raw data has to be extracted, cleaned, reconciled, and reshaped before anyone should trust it. There are two dominant patterns. In ETL (extract, transform, load), data is transformed in a dedicated processing layer before it is loaded into the warehouse, the traditional approach. In ELT (extract, load, transform), raw data is loaded into the warehouse first and transformed there, using the warehouse's own considerable compute. ELT has become the default in the cloud, where storage is cheap and processing power scales on demand. Many designs use a staging area: a landing zone where incoming data is consolidated and cleansed before it moves into the warehouse proper. Historically these loads ran nightly or weekly in batches; today many pipelines run continuously, through micro-batches, streaming ingestion, and change data capture, so the warehouse stays close to real time.
Storage: the warehouse itself. Cleaned, integrated data lands here, modeled for analysis. Modern warehouses store data in columnar format and spread each query across many machines using massively parallel processing (MPP), which is what lets a single query crunch billions of rows in seconds.
Access layer and BI tools. On top sits the layer people actually touch: SQL, dashboards, reports, spreadsheets, notebooks, and the analytical and machine-learning models that consume warehouse data. A semantic layer gives everyone consistent definitions of shared metrics like "revenue" or "active customer," so different teams stop arriving at different numbers.
Three reference architectures
These pieces can be assembled at different levels of sophistication, and most real warehouses grow through three broadly recognized stages.
The basic architecture lets end users query consolidated data directly: source data flows into one warehouse, and people analyze it there. The next step adds a staging area: a dedicated zone to clean and consolidate operational data from multiple sources before it enters the warehouse, which is almost essential once you're integrating many systems. The most elaborate step adds data marts on top of the warehouse, tailored to particular groups (sales, finance, marketing) so each team gets a focused, high-performance slice. Those marts can be physically built as separate tables or defined purely as logical views, and they can sit alongside the central warehouse or run as separate systems.
Two philosophies for modeling the warehouse
How you structure the data inside the warehouse has been debated for as long as warehouses have existed. Two schools of thought dominate.
The Inmon (top-down) approach builds a single, highly normalized enterprise warehouse first, one integrated model in third normal form, and then spins off dimensional data marts from it for individual departments. It emphasizes enterprise-wide consistency up front. It takes longer to deliver initial value but scales cleanly.
The Kimball (bottom-up) approach starts from the business questions and builds dimensional data marts first, using star schemas, then ties them together through shared, or "conformed," dimensions. It delivers value faster and tends to be easier for business users to understand.
Both revolve around dimensional modeling for the analytical layer. Fact tables hold the measurements (a sale, a shipment, a click) while dimension tables hold the context: who, what, when, and where. Arrange one fact table surrounded by its dimensions and you get a star schema; normalize those dimensions into sub-tables and you get a snowflake schema. A related idea worth knowing is grain: the level of detail a fact table records (one row per order line, per day, per transaction), which you should decide deliberately because it governs what questions the model can answer.
Most teams today blend the two philosophies rather than treating the choice as a religious war, and cloud economics have taken much of the heat out of the debate, because storage and compute are no longer scarce enough to force the trade-offs that once did.
Coming up next
Architecture and modeling explain how a warehouse works in principle. But the last decade rewired how they're actually delivered. In Part 3, The Modern Cloud Data Warehouse, we look at how the cloud separated storage from compute, why the line between warehouse, lake, and lakehouse blurred, and what governance and cost discipline a modern build requires.